Evaluation depends on task and embodiment
Success varies by task, robot, sensors, and action space. Benchmarks must control for each.
 FIELDrun
Evaluate. Adapt. Deploy.
We help robotics companies evaluate, fine-tune, and deploy robot policies on their own hardware.
Different robots. Different interfaces. Limited onboard compute.
Success varies by task, robot, sensors, and action space. Benchmarks must control for each.
VLA inputs and actions must map to robot observations, coordinate frames, joint order, and control APIs.
Failures require triage and annotation before they become policy-compatible fine-tuning data.
Policies must meet onboard memory, throughput, and control-loop latency budgets without losing task performance.
A focused deployment stack for robotics teams.
EVALUATION & POST-TRAINING
Benchmark VLA policies across tasks and robot setups.
EXPLORE FIELDARENA ↗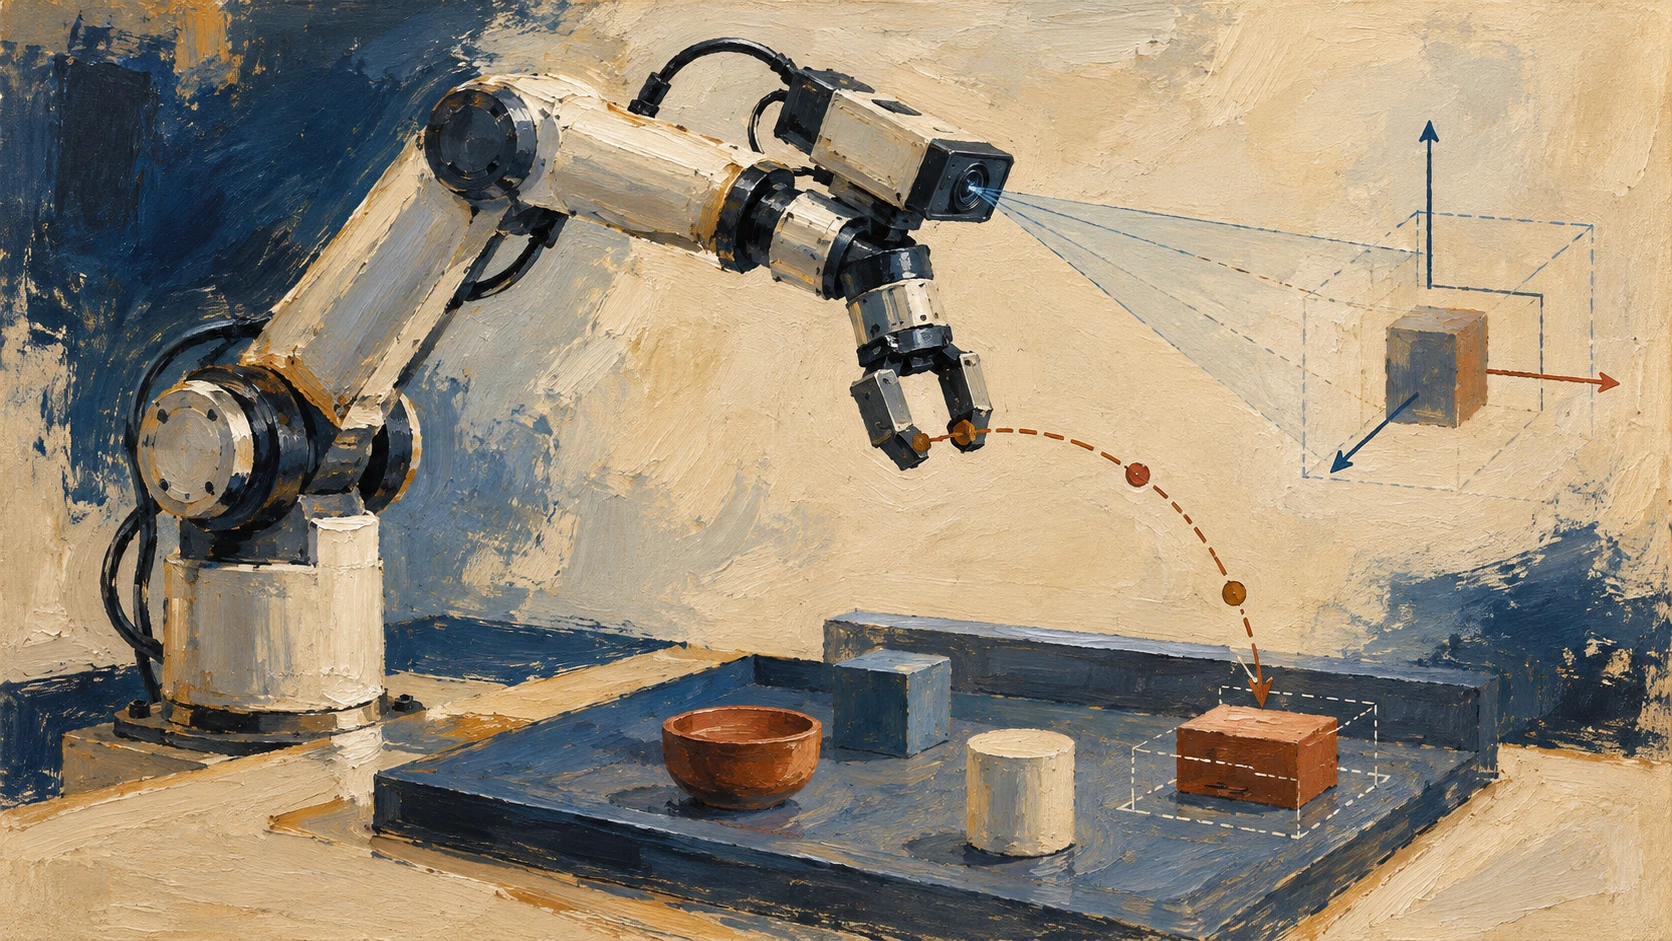
POLICY-TO-ROBOT ADAPTATION
Map policy observations and actions to each robot’s sensors, frames, and control API.
EXPLORE FIELDADAPT ↗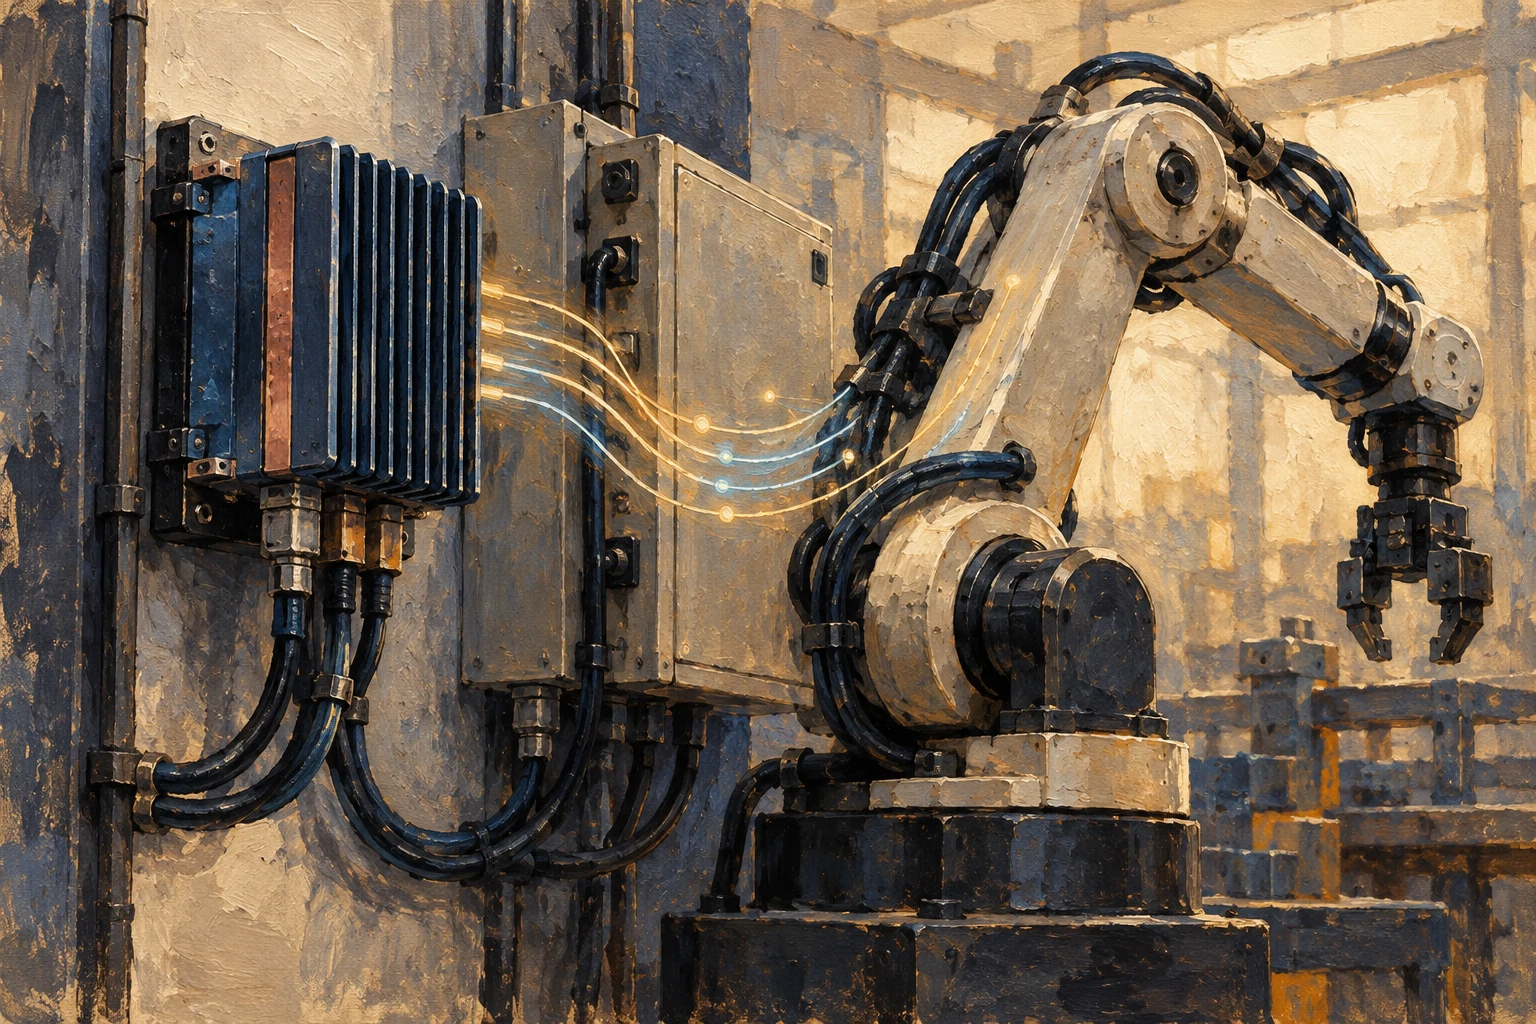
ON-ROBOT INFERENCE
Optimize policy inference for the target robot’s compute and control-loop budgets.
EXPLORE FIELDEDGE ↗Watch learned policies handle tabletop manipulation tasks on physical robots.
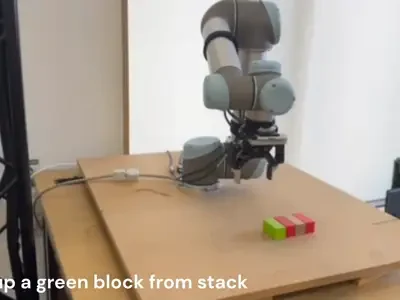 01 / BLOCK STACKING
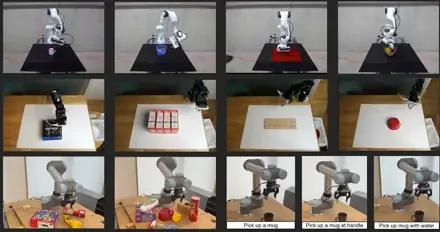 02 / MULTI-TASK MANIPULATION
Built for robotics teams that want better AI without building every part of the stack themselves.
Request early access ↗
Tell us what you’re building and where deployment gets difficult.